16 Lesson 16: Administration / Localization
This page is extracted from the official PDF into native Markdown. Slide text, code and speaker notes are kept in reading order; the original PDF and HTML remain the layout references. HTML source: dba2_16_admin_localization.html Archive: DBA2-handouts-16-en.zip PDF pages: 32
Page 1: Administration / Localization
Copyright
© Postgres Professional, 2016–2026 Authors: Egor Rogov, Pavel Luzanov, Ilya Bashtanov, Igor Gnatyuk Translated by: Elena Sharafutdinova Photo: Oleg Bartunov (Phu Monastery and Bhrikuti Peak, Nepal)
Use of Course Materials
Non-commercial use of course materials (presentations, demonstrations) is allowed without restrictions. Commercial use is possible only with the written permission of Postgres Professional. It is prohibited to make changes to the course materials.
Feedback
Please send your feedback, comments and suggestions to: edu@postgrespro.ru
Disclaimer
Postgres Professional assumes no responsibility for any damages and losses, including loss of income, caused by direct or indirect, intentional or accidental use of course materials. Postgres Professional company specifically disclaims any warranties on course materials. Course materials are provided “as is,” and Postgres Professional company has no obligations to provide maintenance, support, updates, enhancements, or modifications.
Page 2: Topics
- Function of Localization
- Locales and their Categories
- Locale Providers
- Server Configuration
- Dates, Numbers and Currency Amounts
- Client Configuration
- Server and Client Messages
- Collations
Page 3: Function
Character encoding support
- character encodings for different languages
- character set conversion between server and client
- Locale-dependent functionality
- character sorting and comparison
- upper, lower, and initcap functions
- pattern matching
- to_char functions for dates, numbers, and currency amounts
- language for server and utility messages
Speaker notes
PostgreSQL localization features allow storing text in various character encodings. For example, for the French language all major character encodings are supported, including UTF8, LATIN1 (ISO 8859-1), LATIN9 (ISO 8859-15), and WIN1252.
A client application can operate in an encoding different from the server’s encoding. In such cases, character conversion between the client and server is performed automatically.
Beyond supporting various encodings, localization affects the operation of the following server functionalities:
● Character sorting, such as in ORDER BY clauses or in comparison operations (>, <)
● Case conversion in the upper, lower, and initcap functions
● Pattern matching in regular expressions and LIKE, SIMILAR TO operators, including case-insensitive search
● Formatting of dates, numbers, and currency amounts in the to_char functions
● Selecting the language for server and utility messages
https://postgrespro.com/docs/postgresql/current/multibyte#MULTIBYTE-CH ARSET-SUPPORTED
https://postgrespro.com/docs/postgresql/16/locale
Page 4: Locales and their Categories
Locales
- define the language, region, and character encoding,
- for example, fr_FR.UTF8
- installed in the operating system
- Locale categories and their corresponding parameters
- LC_COLLATE
- string sort order
- LC_CTYPE
- character classification
- LC_MESSAGES
- lc_messages
- language of messages
- LC_MONETARY
- lc_monetary
- formatting of currency amounts
- LC_NUMERIC
- lc_numeric
- formatting of numbers
- LC_TIME
- lc_time
- formatting of dates and times
Speaker notes
PostgreSQL relies on the localization capabilities provided by the operating system. Therefore, the locales required for the DBMS should be pre-configured in the OS.
Locales in the OS are typically specified in the “language_region.encoding” format. For example, fr_CA.UTF8 represents the French language as spoken in Canada (CA). Windows uses verbose locale names, such as French_Canada.1252.
The language and region determine cultural preferences such as character order, date formats, decimal separators, etc.
Sometimes it is necessary to combine the behavior of different locales. For example, to use French date and time formats while keeping server messages in English. PostgreSQL supports setting locale categories separately via corresponding configuration parameters of the same name.
Starting with PostgreSQL 16, the unchangeable server parameters for the LC_COLLATE and LC_CTYPE locale categories have been removed. To obtain information about a database’s locale now, you should query the pg_database system catalog table.
Page 5: Locale Providers
Standard libc library
- POSIX compliance
- External ICU library
- portable solution
- extensive additional features
Speaker notes
PostgreSQL supports various locale providers. Providers are libraries that supply locale data and implement sorting. The standard libc provider uses the system’s C library and provides its locales. These locales are used by most operating system utilities.
PostgreSQL also supports the ICU provider, which uses the external ICU library. ICU locale names are based on the IETF BCP 47 language tag standard. These tags have formats “language-region” or simply “language” (for example, fr-FR). When using ICU locales, PostgreSQL validates the names and transforms them to their canonical form according to the standard rules. The icu_validation_level parameter controls the message level for locale validation checks.
https://postgrespro.com/docs/postgresql/16/locale#ICU-LANGUAGE-TAG
https://www.rfc-editor.org/rfc/bcp/bcp47.txt
Information about the selected provider and database locale is stored in the pg_datlocprovider and daticulocale columns of the pg_database table. For several reasons, libc settings are required in all databases (even those using the ICU provider), so the datcollate and datctype columns always contain information about the libc locale.
Commands and utilities for setting locale parameters also allow us to explicitly select the provider. The libc provider is used by default.
https://postgrespro.com/docs/postgresql/16/locale#LOCALE-PROVIDERS
Page 6: Server Configuration
 {#source-figure-006 caption=“Source slide page 6: Server Configuration”}
Speaker notes
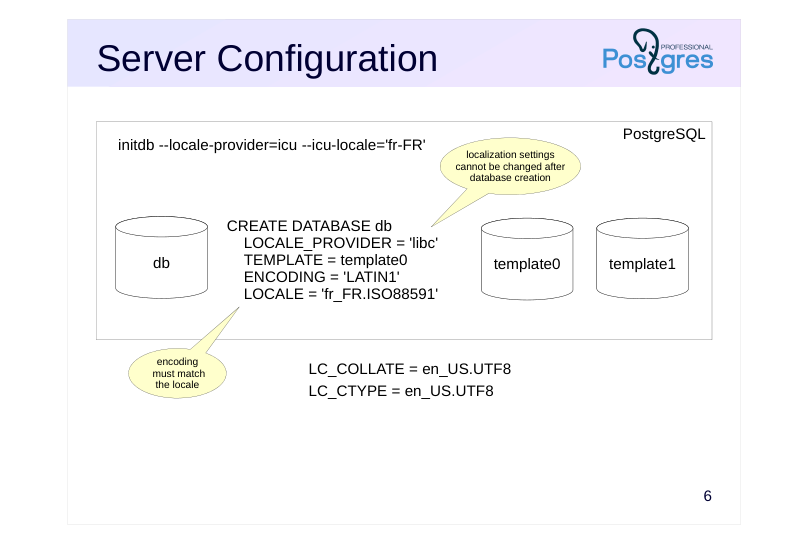
When initializing the cluster, the provider and locale for template databases are set using options of the initdb utility. By default, the system uses the libc provider and the locale from the OS environment.
When a database is created, it inherits the localization settings of its template. To create a database with different localization settings, we should use the template0, as it is guaranteed not to contain any locale-specific data. We can change the provider, character encoding, and the LC_CTYPE and LC_COLLATE locale categories. Since the category values are typically the same, it is convenient to set them using a single parameter (option): LOCALE for libc and ICU_LOCALE for ICU.
The database encoding must be compatible with the LC_CTYPE and LC_COLLATE locale parameters of that database. The C and POSIX locales are compatible with any character set, while other libc provider locales each have only one character set that will function correctly. (An exception: on Windows, UTF-8 encoding can be used with any locale.) ICU provider locales are compatible with most encodings.
Page 7: Locales and Categories
The server OS already has locales installed with the French language support:
The localization parameters for the OS session are controlled by environment variables:
In addition to variables corresponding to locale categories, there are special variables: LC_ALL — when set, overrides all locale categories, even if they have been explicitly specified LANG — used for any locale categories that have not been explicitly set LANGUAGE — when set, takes precedence over LC_MESSAGES (explained in detail later) When PostgreSQL was installed from the package in the course VM, the main cluster was initialized using the OS session parameters and the libc provider. To set different values, you can use the –locale-provider, –locale (equivalent to LANG), and options for specific categories, for example:
PostgreSQL has four parameters that correspond to locale categories of the same name. Notice that there are fewer of them than in the OS:
These parameter values are written to the configuration file. Any user can modify the lc_monetary, lc_numeric, and lc_time parameters (context=user), while lc_messages can be changed only by a superuser. There are no corresponding server parameters for the LC_COLLATE and LC_CTYPE locale categories. When a backend starts, it resets the LC_ALL value and sets the OS environment variables for locale categories according to the lc_* configuration parameters. When a parameter is changed during a session, the backend sets the corresponding environment variable to match. The standard postgres, template0, and template1 databases use the LC_COLLATE and LC_CTYPE values, as well as the locale provider, that were set during cluster initialization. New databases by default copy the parameters of the template they use:
Page 8: Page 8
Dates and LC\_TIME
Configuration parameter for the corresponding locale category:
To use English month and day names in the to_char function’s format mask, add the TM prefix:
The same for French:
Reset the parameter to its original value:
The to_date and to_char functions let you explicitly specify the date and time format for input/output. The datestyle parameter affects implicit conversion between dates and text. Here are a few examples:
Page 9: Page 9
Numbers and LC\_NUMERIC
Configuration parameter for the corresponding locale category:
The following digit group separators (G) and decimal separators (D) are used in France:
The same for the United States:
Currency Amounts and LC\_MONETARY
Configuration parameter for the corresponding locale category:
The money data type adds a currency code to the amount:
However, note that a table with this type can store only one currency, which will change along with the LC_MONETARY:
Page 10: Page 10
Page 11: Client Configuration
 {#source-figure-011 caption=“Source slide page 11: Client Configuration”}
Speaker notes
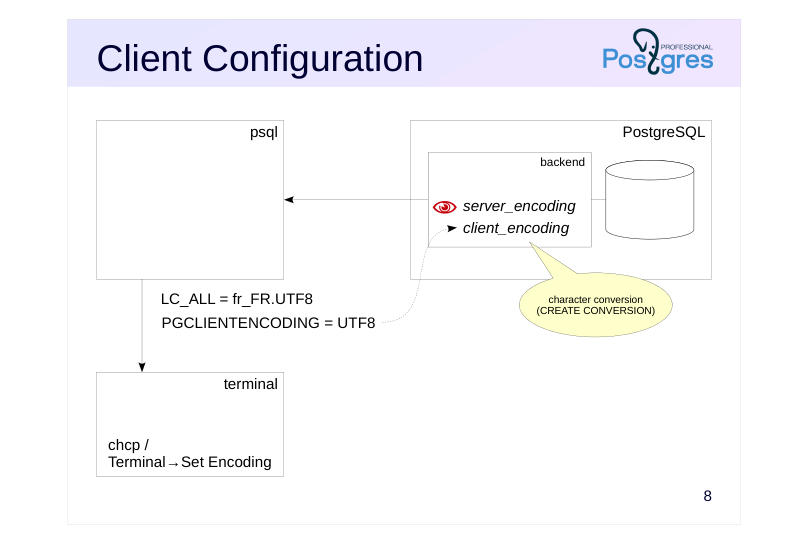
To configure localization for a client application, we need to do the following.
● Check that the server settings are correct. As a minimum, ensure the correct database encoding is used (the unchangeable server_encoding parameter shows the encoding set when the database was created).
● Check that the required locales are installed in the client OS and configure the locale categories (the LC_* environment variables) in the OS session.
● Configure the application’s encoding and check the settings of the output device.
For example, psql on Windows may use the Windows-1252 encoding, in this case in the terminal (cmd.exe) run the chcp 1252 command and set a true type font (e.g., Lucida Console).
● After connecting to the database, check the client_encoding parameter. This parameter controls character set conversion between the client and server. If needed, set it to the application’s encoding. The client_encoding value can also be set using the PGCLIENTENCODING environment variable.
The backend automatically converts character set between the database encoding (server_encoding) and the client encoding (client_encoding). PostgreSQL comes preconfigured with the necessary character conversion routines for most encoding pairs, which are stored in the pg_conversion system catalog table. We can define an additional conversion routine using CREATE CONVERSION, though this is rarely needed in practice.
Page 12: Client and Server Working with Different Encodings
Create a database with LATIN1 encoding, while the client continues to use UTF8. Specify ICU as the locale provider. To create the database successfully, we need to use the template0: it is an empty database where indexes are guaranteed not to be corrupted by the encoding change:
In our case (creating a database with the ICU provider), we needed to specify the LC_CTYPE and LC_COLLATE parameters to match the chosen encoding.
Connect to admin_localization_latin1 and check that character conversion is working properly.
Client and server encodings:
The client (psql) sets the value of the client_encoding parameter. In interactive mode, the value is set based on the client’s encoding (the LC_CTYPE variable in the OS). But when running from a script, as in this demo, it is set to the database encoding. Let’s explicitly set the value to match the client locale:
Now characters will be correctly converted from UTF8 to LATIN1 and back:
Page 13: Page 13
List of available encoding conversions for LATIN1:
Page 14: Server Messages
 {#source-figure-014 caption=“Source slide page 14: Server Messages”}
Speaker notes
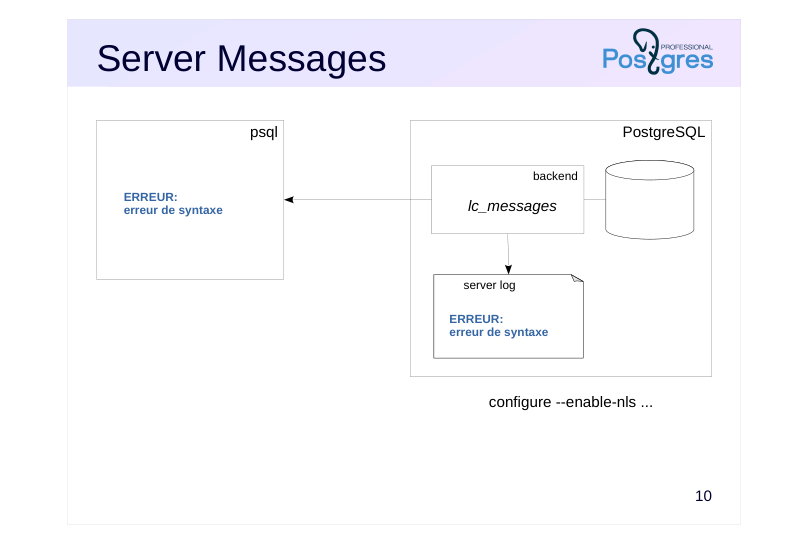
PostgreSQL server (and utility) messages are translated into several languages.
To display server messages in French, the PostgreSQL server must be compiled with national language support enabled (configure –enable-nls). Most packages are built with this option enabled.
The lc_messages configuration parameter controls the language of server messages.
Server messages are not only sent to the client but also recorded to the server log. When selecting a language other than English, make sure that your server log analysis tools support that language. For example, pgBadger works only with English messages.
More information on server message translation for translators and developers: https://postgrespro.com/docs/postgresql/16/nls
Page 15: Utility Messages
 {#source-figure-015 caption=“Source slide page 15: Utility Messages”}
Speaker notes
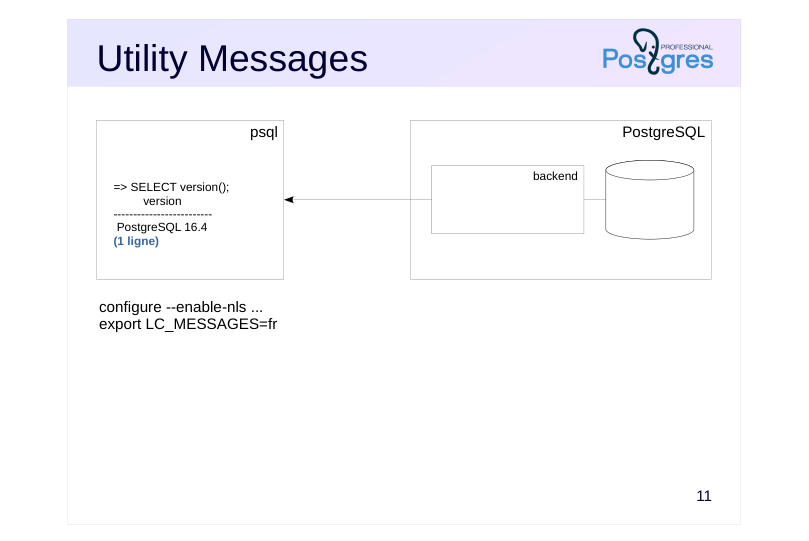
PostgreSQL utilities (psql, pg_dump, etc.) also support multiple languages.
To display utility messages in a language other than English, the PostgreSQL client must be compiled with NLS support. The output language is set on the client via the LC_MESSAGES environment variable (the server parameter lc_messages affects only the server’s own messages, not the client’s).
Most operating systems (including Windows) check environment variables for message language in the following order: LANGUAGE, LC_ALL, LC_MESSAGES, LANG.
Page 16: Server and Client Messages
Server messages can be displayed in different languages. First, make sure that PostgreSQL was built with NLS support:
List of available languages and their message files can be found here:
Page 17: Page 17
To log a message, we use an incorrect command:
The server log records the same error message and the failed command itself. To display messages in French, change the lc_messages parameter.
Now the message is displayed to the client and logged in French. Look at the messages displayed by the psql client. They remain in English:
The language for messages from a client built with NLS support is determined by the LC_MESSAGES and LANGUAGE OS environment variables, with LANGUAGE taking precedence:
To fully localize the environment, set French for psql messages.
Now all messages are displayed in French.
Page 18: Collations
Database objects
- multiple collation rules within a single database
- populated during database creation
- Usage
- cluster
- database
- table column
- expression
- Standard collations
- default, C, POSIX
- unicode, ucs_basic
Speaker notes
PostgreSQL provides special objects called collations that enable different sorting and comparison methods for textual data within a single database.
Collations allow using a sort order different from the database default. They can be applied to table columns, domain definitions, and directly in expressions that sort or compare text strings. When creating a new collation, we specify the provider and character classification.
The initial set of collations is created during cluster initialization: collations are loaded for all locales available in the OS. Later, when new locales are added to the OS, we can load their collation rules into the database.
The standard C and POSIX collations behave identically and they are created for all server encodings. Under these collations, only Latin characters from A to Z are treated as letters, while all other characters are sorted according to their code points in the given encoding. The collation named default uses the LC_COLLATE, LC_CTYPE, and provider values defined at database creation. Additionally, the unicode and ucs_basic collations defined in the SQL standard are also available.
All available collations can be viewed in the pg_collation system catalog table.
https://postgrespro.com/docs/postgresql/16/collation
Page 19: libc Provider
Character order
- depends on the implementation in the OS
- library version is tracked
- Used by default
- for the cluster and database
Speaker notes
Collations in PostgreSQL that use the libc provider behave identically to those in the OS. However, various OS may implement the libc library differently. Consequently, sorting for the same locales may differ depending on the database server’s OS. If an application needs to support database operations across different operating systems (including logical replication), make sure that collation works consistently across all platforms.
A more serious potential issue is installing a new version of the libc library in the OS. For example, this can happen when migrating to a server with a newer OS version. Changes to the collations used by the database in the new libc version can lead to incorrect index operation and other issues.
Page 20: ICU Provider
Character order
- depends on the library version rather than the OS
- library version is tracked
- Additional features
- control over the sorting order of character groups
- custom collations
Speaker notes
To use the ICU provider for collations, PostgreSQL must be built with ICU library support. The ICU library and its collations work identically across all operating systems.
The ICU library allows modifications to collations without changing the language or region. We can specify different sorting orders for individual character groups. For example, which character group should come first: letters, digits or currency symbols; uppercase or lowercase letters. We can configure these rules by including the corresponding parameters in the language tag.
Additional collations are defined using a special syntax, with examples provided in the demonstration.
https://postgrespro.com/docs/postgresql/16/collation#ICU-CUSTOM-COLLA TIONS
Page 21: Collations
Let’s unset the variable and restart psql to return to English.
During cluster initialization, special objects called collations are created in the system catalog of each database, based on the information about locales installed in the OS. Initial collations in the database:
Collations for French obtained from the OS:
Page 22: Page 22
Note Note that only collations compatible with the current database’s encoding are displayed, so the command output may vary for different databases within the same PostgreSQL instance. Collations for the ICU provider are created only if the server was built with –with-icu option. Such collations are named using a language tag with an “-x-icu” suffix to distinguish them from libc locales.
Page 23: ICU Collations
The sorting order for the default collation differs from the order for fr-CA-x-icu. Accents are usually compared left-to-right, but in Canadian French they are compared right-to-left:
The COLLATE keyword following an expression (in ORDER BY) explicitly specifies the collation. By default, the collation set in database locale parameters is used. ICU library capabilities allow flexible customization of sorting for specific character groups by defining new collations with parameters specified as part of a language tag. Default sort places digits and letters after currency symbols:
Create a new collation where currencies come after digits:
And another collation where, in addition to the previous one, letters come before digits:
Check the sorting:
If the collation parameters mentioned above do not meet your needs, you can customize the sort order by defining specific collations:
Page 24: Page 24
Page 25: Determinism
Deterministic collations
- string equality is based on byte-for-byte match
- Non-deterministic collations
- strings consisting of different bytes can be considered equal
- greater flexibility
- lower performance
- do not support LIKE and other operations
Speaker notes
A collation can be either deterministic or non-deterministic, depending on the type of comparison.
Deterministic comparisons consider strings equal only if they consist of identical bytes. In non-deterministic comparisons, strings can be considered equal even if their byte sequences differ. For example, in Unicode the French letter é (e-acute) can be represented either as a single character, Latin Small Letter E with Acute (U+00E9), or composed of the regular letter “e” (U+0065) combined with the acute accent (U+0301).
All standard collations are deterministic. Custom collations are also deterministic by default.
Non-deterministic collations offer greater flexibility: for instance, we can define a unique constraint that ignores case or diacritical marks. However, deterministic collations generally provide higher performance. Moreover, non-deterministic collations do not support certain operations, such as pattern matching.
Page 26: Nondeterministic Collations
Define a nondeterministic collation for case-insensitive sorting:
Now strings in different cases can be equal:
However, pattern matching is not possible for non-deterministic collations:
Page 27: Changes Tracking
Changing the provider library causes issues with:
- sorting of index keys
- string comparisons in integrity constraints
- string comparisons in queries,
- etc.
- The library version number is stored in the system catalog
- When the installed version changes, a warning is issued
- libc does not guarantee version stability and cross-platform compatibility
Speaker notes
Changes in the provider library that alter comparison behavior can affect the collations used in the database and lead to the following problems:
● Incorrect query execution due to broken ordering of index keys
● Data corruption due to changed string comparison behavior in CHECK constraints and triggers
● Incorrect results due to changed string comparison behavior in queries, procedural code, and row-level security policies
To prevent data corruption, PostgreSQL issues warnings when library changes might affect existing collations.
When a collation is created, the current version number of the library is stored in the system catalog, in the pg_collation and pg_database tables. Each time the collation is used, the stored version number is compared with the current one, and warnings are generated if they do not match.
If a mismatch is detected, you should rebuild any indexes that use the changed collation, and also review all procedures, constraints, and queries that use that collation.
It is important to remember that, unlike ICU, the libc provider does not guarantee consistent collation behavior even when library versions match.
Page 28: Changes in Provider Libraries
When a collation is created, the library version reported by the OS is stored in the system catalog. If the library version changes in the OS, a warning about the version mismatch will be issued every time the collation is used. You can compare versions with a query:
Changes in a collation can lead to incorrect index operation. If this happens, it is recommended to rebuild indexes using the new version of the collation. After that, you can update the version in the system catalog using the ALTER COLLATION … REFRESH VERSION, and warnings will no longer be displayed. Query to get a list of objects that depend on collations requiring an update:
The same check is performed for collations at the database level. The pg_database_collation_actual_version function shows the current collation version in the OS:
If the version of the collation set for the database does not match the library version in the OS, a warning is issued when connecting to the database. In this case, it is recommended to rebuild indexes that use the default collation. After that, you can update the version number stored in pg_database using the ALTER DATABASE … REFRESH COLLATION VERSION.
Page 29: Takeaways
The necessary locales for the DBMS must be installed in the OS before initializing a cluster
- The client and server can operate using different character encodings with automatic character conversion
- Server and client messages are available in many languages
- Collations rely on external libraries, and changes to these libraries can result in data corruption and incorrect results
Page 30: Practice
- Transfer data between databases with different encodings.
- Create a database using the LATIN1 character encoding.
- Create a table and insert rows containing French accent
- characters. Create a backup of the database using the pg_dump
- utility. Restore the table from the backup into a database with
- UTF8 encoding.
- Get the number for today’s day of the week. Does this number depend on localization settings?
Speaker notes
- To create a database with LATIN1 encoding:
● Make sure the required locale is installed in the OS.
● In the CREATE DATABASE command, use the template0 and the ENCODING and LOCALE parameters.
- Use the to_char function to get the day of the week number.
Valid date format patterns:
https://postgrespro.com/docs/postgresql/16/functions-formatting#FUNCTION S-FORMATTING-DATETIME-TABLE
Page 31: 1. Database Encodings
Let’s check that the OS has locales with iso88591 encoding:
Create databases with LATIN1 and UTF8 encodings:
Connect to the database with LATIN1 encoding:
Check that the client and server use different encodings:
Create a table containing a string with French accents:
Page 32: Page 32
Create a logical backup:
The backup content is exported in the database encoding (LATIN1), and the file begins with a command that sets the client_encoding parameter to match that same LATIN1 value. Restore the table into the admin_localization_utf8 database:
Because client_encoding is set during restoration, characters are automatically converted. Let’s check that the French accents were transferred correctly:
2. Get the Day of the Week Number
Current date and time localization settings:
There are two format patterns for getting the day of the week number: ID — week starts on Monday D — week starts on Sunday
The day of the week number does not depend on localization settings, including the lc_time parameter: