14 Lesson 14: Locks / Locks in RAM
This page is extracted from the official PDF into native Markdown. Slide text, code and speaker notes are kept in reading order; the original PDF and HTML remain the layout references. HTML source: dba2_14_locks_memory.html Archive: DBA2-handouts-16-en.zip PDF pages: 20
Page 1: Locks / Locks in RAM
Copyright
© Postgres Professional, 2016–2026 Authors: Egor Rogov, Pavel Luzanov, Ilya Bashtanov, Igor Gnatyuk Translated by: Elena Sharafutdinova Photo: Oleg Bartunov (Phu Monastery and Bhrikuti Peak, Nepal)
Use of Course Materials
Non-commercial use of course materials (presentations, demonstrations) is allowed without restrictions. Commercial use is possible only with the written permission of Postgres Professional. It is prohibited to make changes to the course materials.
Feedback
Please send your feedback, comments and suggestions to: edu@postgrespro.ru
Disclaimer
Postgres Professional assumes no responsibility for any damages and losses, including loss of income, caused by direct or indirect, intentional or accidental use of course materials. Postgres Professional company specifically disclaims any warranties on course materials. Course materials are provided “as is,” and Postgres Professional company has no obligations to provide maintenance, support, updates, enhancements, or modifications.
Page 2: Topics
- Locks in RAM
- Wait Event Monitoring
Page 3: Locks in RAM
 {#source-figure-003 caption=“Source slide page 3: Locks in RAM”}
Page 4: Spinlocks
Acquired for short periods
- a few CPU instructions
- Exclusive mode
- Monitoring is available
- pg_stat_activity
- No deadlock detection
- Spin loop
- atomic CPU instructions are used
Speaker notes
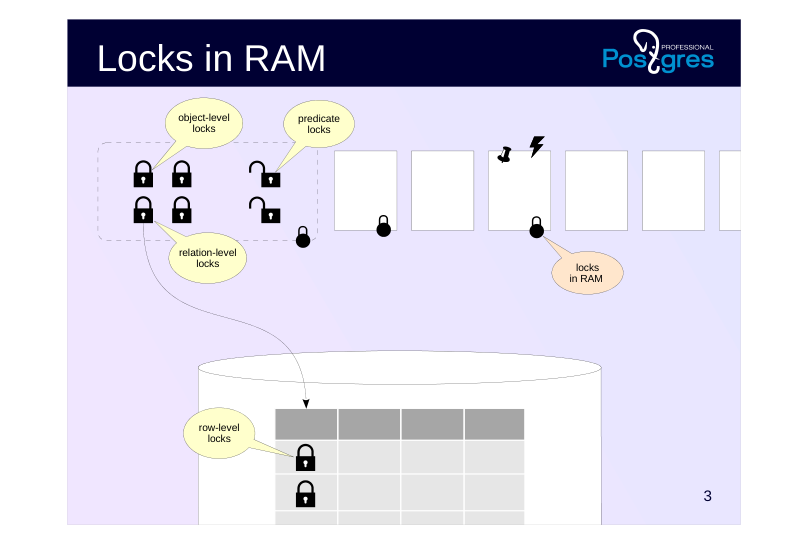
We have already covered long-term locks which typically remain active until the end of a transaction and support multiple modes. Simpler locks with lower overhead are used to protect data structures in shared memory accessed by multiple processes.
The simplest of them are spinlocks. They are meant to be acquired for very short time intervals (a few CPU instructions), they protect individual data fields from simultaneous changes.
Spinlocks are implemented using atomic CPU instructions, such as compare-and-swap (https://en.wikipedia.org/wiki/Compare-and-swap).
They can be acquired only in exclusive mode. If the resource is locked, the process enters an active waiting loop, repeatedly attempting to acquire the lock until it succeeds. This approach makes sense since spinlocks are used only in cases where the probability of a conflict is estimated as very low. There is also monitoring available for tracking wait events related to spinlocks.
However, spinlocks do not provide deadlock detection; preventing such scenarios is the responsibility of PostgreSQL developers.
Page 5: Lightweight Locks
Acquired for short periods
- typically fractions of a second
- Exclusive and shared modes
- Monitoring is available
- pg_stat_activity
- No deadlock detection
- “Unfair” queue
- shared locks allow read processes to bypass the queue
Speaker notes
The next category is lightweight locks (lwlocks).
They are acquired for a short period to work with a data structure (such as a hash table or a list of pointers). Lightweight locks are typically held for a short time, but during that time IO operations may occur, so the duration can sometimes become significant.
Two locking modes are supported: exclusive (for writing) and shared (for reading).
A wait queue is supported. However, while the lock is held in shared mode, other reading processes can bypass the queue. In highly concurrent systems under heavy load, this can lead to unpredictably long waits for processes that need to modify data (https://postgrespro.com/list/thread-id/2400193).
Deadlock detection is not provided, just as with spinlocks. Monitoring is available for lightweight locks.
Page 6: Buffer Pin
Acquired for the duration of buffer operations
- potentially for an extended period
- Shared mode
- Monitoring is available
- pg_stat_activity
- pg_buffercache
- No deadlock detection
- Passive waiting
- a pinned buffer is typically skipped
Speaker notes
Another type of lock, which we already covered in the Buffer Cache lesson of the WAL module is the buffer pin.
A list of processes working with the buffer is maintained for each buffer. Certain operations are prohibited on a pinned buffer. For example, we can insert a new row into a page (which other processes will not see due to MVCC), but we cannot replace a page with another one.
Typically, processes skip a pinned buffer and choose another one to avoid waiting. However, in some cases where a specific buffer is required, a lightweight lock in exclusive mode is requested. If necessary, the process waits until all other processes finish working with the buffer. This waiting is passive: the system wakes up the waiting process when the buffer is unpinned.
Deadlocks are impossible here, preventing such scenarios is the responsibility of PostgreSQL developers.
Wait events related to buffer pins can be monitored using the pg_stat_activity view. The current number of buffer pins is shown by the pg_buffercache extension.
Page 7: Example: Buffer Cache
 {#source-figure-007 caption=“Source slide page 7: Example: Buffer Cache”}
Speaker notes
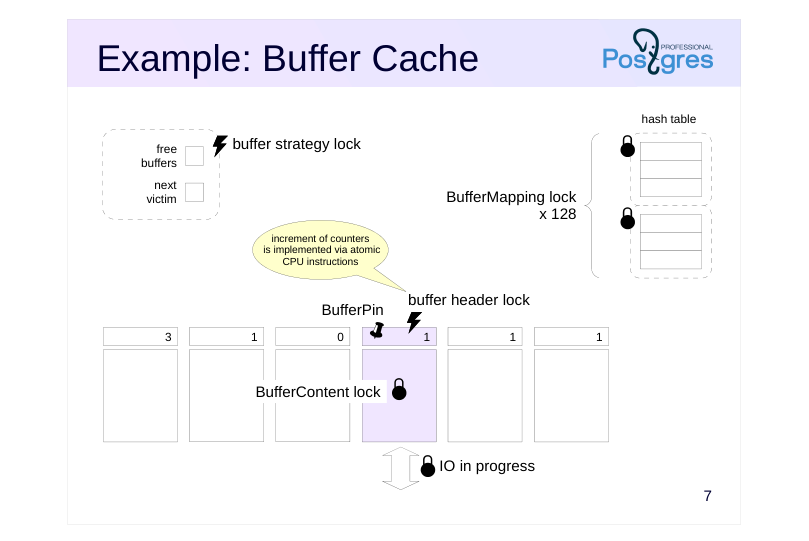
To get a basic (incomplete) understanding of how and where locks are used, let’s look at the buffer cache as an example.
To access the hash table containing references to buffers, the process should acquire a lightweight BufferMapping lock in shared mode; or in exclusive mode if the table needs to be modified. To increase granularity, this lock is implemented as a tranche of 128 separate locks, each protecting its own portion of the hash table.
A process accesses a buffer header using a spinlock. Some operations (such as incrementing a counter) can be performed without explicit locks, using atomic CPU instructions.
To read the buffer’s contents, a BufferContent lock is required. Typically, it is acquired to read only item pointers, and after that, a buffer pin provides sufficient protection. To change the buffer contents, this lock is acquired in exclusive mode.
When a buffer is being read from disk (or written to disk), the IO in progress flag is set in its header. This signals to other processes that the page is being read, so they can queue up if they need the same page.
Pointers to free buffers and to the next victim are protected by a single spinlock called the buffer strategy lock.
Page 8: Example: WAL Buffers
 {#source-figure-008 caption=“Source slide page 8: Example: WAL Buffers”}
Speaker notes
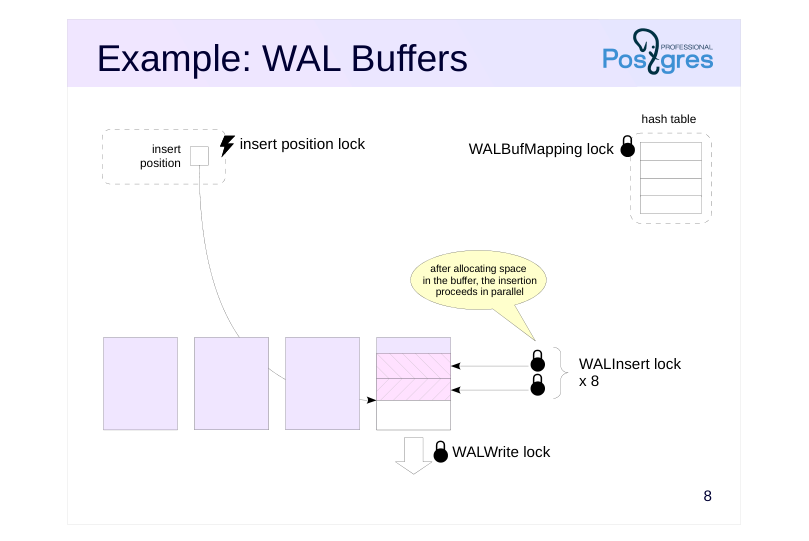
WAL buffers provide another example.
The WAL cache also uses a hash table that contains mapping of pages to buffers. Unlike the buffer cache’s hash table, this hash table is protected by a single lightweight WALBufMapping lock, since the WAL cache is smaller (usually 1/32 of the buffer cache) and access to the buffers is more sequential.
Writing pages to disk is protected by the lightweight WALWrite lock, so that only one process can perform this operation at a time.
To create a WAL record, the process must first allocate space in a page. To do this, it acquires an insert position spinlock. When the space is allocated, the process copies the contents of the record into it. Copying can be performed by several processes simultaneously, therefore, recording is protected by a tranche of eight lightweight WALInsert locks.
The figure does not show all WAL-related locks, but this and previous examples should give a basic idea of how locks in RAM are used.
Page 9: Wait Event Monitoring
Wait events in pg\_stat\_activity and sampling
- Wait event types
Page 10: Wait Event Sampling
When a process is waiting for something, this information appears in the pg\_stat\_activity view
- wait_event_type — type of wait event
- wait_event — name of the specific wait event
- The information may be incomplete
- not all code locations where wait events can occur are covered
- The information reflects only the current moment
- the only way to observe behavior over time is through sampling
- a reliable picture emerges only with a large number of measurements
Speaker notes
The pg_stat_activity view is used for monitoring wait events. When a process (system or backend) cannot proceed with its work and is waiting for something, that wait event appears in the view. The wait_event_type column shows the type of wait event, while the wait_event column shows the name of the specific wait event.
Note that the view shows only waits that are properly handled in the source code. If the view does not show a wait event, this does not guarantee with 100% certainty that the process is not waiting for something.
Unfortunately, the only available information about wait events is the current information. No cumulative statistics are maintained. The only way to get a picture of wait events is sampling the state of the view at regular intervals. While there is no built‐in tool for this, extensions like pg_wait_sampling can be used.
https://github.com/postgrespro/pg\_wait\_sampling
Remember that sampling has a probabilistic nature: to get a reasonably reliable picture, the number of samples must be sufficiently high. Therefore, low‐frequency sampling does not provide accurate data, while increasing the frequency leads to higher overhead. For the same reason, sampling is useless for analyzing short-lived sessions.
Page 11: Wait Event Types
Locks
- pg_stat_activity.wait_event_type
- object lock
- Lock
- lightweight lock
- LWLock
- buffer pin
- BufferPin
- Other wait events
- input/output
- IO
- waiting for data from another process
- IPC
- waiting for data from the client
- Client
- waiting in an extension module
- Extension
- idle waiting
- Activity, Timeout
- Any remaining time is considered unaccounted
Speaker notes
Wait events can be categorized into several types. The locks we have examined represent a major category of wait events: object lock waits (Lock in the wait_event_type column), lightweight locks (LWLock), and buffer pins (BufferPin).
Processes can also wait for other types of events. IO wait events occur when a process needs to read or write data. A process might wait for the data it needs to operate, either from a client (Client) or another process (IPC).
Extensions can register their specific wait events.
There are also situations where a process is simply not doing any productive work. This category includes waits for background processes in their main loop (Activity) and timer waits (Timeout). These types of wait events are typically normal and do not indicate any problems.
Each type of wait event has a specific wait name: https://postgrespro.com/docs/postgresql/16/monitoring-stats#WAIT-EVENT-TABLE
If the name of a wait event is not defined, the process is not in the waiting state. This time should be considered as unaccounted for, since we are actually unaware of what exactly is happening at that moment.
In the following demonstration, we will use the FUSE filesystem (https://github.com/libfuse/libfuse) and the slowfs project based on it (https://github.com/nirs/slowfs) to slow down IO operations.
Page 12: Wait Event Monitoring
We can see current waits in the pg_stat_activity view, which shows information about active processes. Let’s select just a few fields:
Empty values indicate that the process is not waiting and is doing productive work. To get a reasonably complete picture of what a process is waiting for, we need to perform sampling at a certain frequency. Use the pg_wait_sampling extension. The extension is already installed in the OS of the course VM, but we need to add its library name to the shared_preload_libraries configuration parameter. Applying this parameter requires a server restart.
Now create the extension in the database.
The extension allows us to view a short history of wait events, which is stored in a ring buffer. What’s more interesting is to see the wait profile — cumulative statistics for the entire runtime. Let’s wait a few seconds and check the profile…
Given the lack of activity since server startup, most wait events fall into the Activity category (background processes waiting for work to appear) and the Client category (psql waiting for the user to send a query). Rows with empty event_type and event values correspond to situations where the process is not waiting (but it is running and consuming CPU time). The pg_wait_sampling.sample_cpu parameter controls whether these rows are displayed:
Page 13: Page 13
With default settings, the sampling frequency is 100 times per second. Therefore, to estimate wait duration in seconds, divide the count value by 100. To identify which process each wait event belongs to, add the pg_stat_activity view to the query:
Let’s run a load test using pgbench and observe how the picture changes.
Reset the collected profile and run a 30-second test in a separate process. Monitor how the profile changes in real time.
Page 14: Page 14
The wait events for the pgbench process will vary depending on the specific system. In our case, it is most likely to see wait events for WAL writing and synchronization (IO/WALSync, IO/WALWrite).
Lightweight Locks
It is always important to remember that if a wait event does not show up in the sampling data, it does not mean the wait never occurred. If it was shorter than the sampling interval (one hundredth of a second in our example), it might simply not appear in the sample. Therefore, lightweight locks most likely did not appear in the profile, but they would appear if we collected data over a long period. To make sure we see them, let’s connect to the slow cluster with a slowed-down filesystem, where every IO operation takes 1/10 of a second.
Reset the profile again and run the workload.
Page 15: Page 15
Now the main wait for the pgbench process is related to IO, specifically WAL writing, which is performed synchronously with each commit. Since writing WAL to disk is protected by the lightweight WALWriteLock (as we saw in the presentation slide), it also appears in the profile.
Page 16: Takeaways
Locks in RAM are implemented using different mechanisms
- spinlocks, lightweight locks, buffer pins
- short duration and lightweight infrastructure
- Monitoring of current wait events using the pg_stat_activity view
- sampling is required to observe behavior over time
Page 17: Practice
- An open cursor holds a buffer pin so that reading the next row can be performed more quickly. Check this using the pg_buffercache extension.
- Open a cursor on a table and, without closing the cursor, run VACUUM on that table. Will the vacuum wait for the buffer pin to be released?
- Repeat the experiment, this time running VACUUM FREEZE. Check that the buffer pin wait appears in the backend’s wait profile.
Speaker notes
- The pg_buffercache extension was covered in the WAL module, in the Buffer Cache lesson.
https://postgrespro.com/docs/postgresql/16/pgbuffercache
Page 18: 1. Buffer Pinning with an Open Cursor
Let’s start with the preliminary steps. Install the required extensions:
A table, as in previous practices:
Update the balance for account 2, this will create a dead tuple in the page:
Start a transaction, open a cursor, and fetch one row.
Check if the buffer is pinned:
Page 19: 2. Vacuuming a Pinned Buffer
Yes, pinning_backends = 1. Run vacuuming.
As we can see, the dead tuple was not removed: …tuples missed: 1 dead from 1 pages not removed due to cleanup lock contention. If a buffer is pinned, tuples cannot be removed from the page. However, vacuuming does not wait for the buffer to be released, the tuple will be cleaned up during the next vacuum cycle.
3. Freezing a Pinned Buffer
Let’s run vacuuming and freezing:
Vacuuming hangs until the cursor is closed. When an explicit freeze is requested, every page not marked in the freeze map must be processed. Otherwise, it is impossible to advance the pg_class.relfrozenxid horizon.
Page 20: Page 20
Wait event profile:
The BufferPin wait event indicates that vacuuming was waiting for a buffer to be released.