08 Lesson 08: WAL / Buffer Cache
This page is extracted from the official PDF into native Markdown. Slide text, code and speaker notes are kept in reading order; the original PDF and HTML remain the layout references. HTML source: dba2_08_wal_buffercache.html Archive: DBA2-handouts-16-en.zip PDF pages: 28
Page 1: WAL / Buffer Cache
Copyright
© Postgres Professional, 2016–2026 Authors: Egor Rogov, Pavel Luzanov, Ilya Bashtanov, Igor Gnatyuk Translated by: Elena Sharafutdinova Photo: Oleg Bartunov (Phu Monastery and Bhrikuti Peak, Nepal)
Use of Course Materials
Non-commercial use of course materials (presentations, demonstrations) is allowed without restrictions. Commercial use is possible only with the written permission of Postgres Professional. It is prohibited to make changes to the course materials.
Feedback
Please send your feedback, comments and suggestions to: edu@postgrespro.ru
Disclaimer
Postgres Professional assumes no responsibility for any damages and losses, including loss of income, caused by direct or indirect, intentional or accidental use of course materials. Postgres Professional company specifically disclaims any warranties on course materials. Course materials are provided “as is,” and Postgres Professional company has no obligations to provide maintenance, support, updates, enhancements, or modifications.
Page 2: Topics
- Buffer Cache Design and Usage
- Eviction Mechanism
- Bulk Eviction and Buffer Rings
- Tuning
- Local Cache for Temporary Tables
- Cache Prewarming
Page 3: Buffer Cache
 {#source-figure-003 caption=“Source slide page 3: Buffer Cache”}
Speaker notes
The function of the buffer cache is to smooth out the difference in performance of two types of memory: RAM (fast, but limited) and disk storage (slow, but large). To work with data, whether reading or modifying it, processes read pages into the buffer cache. While the page is in the cache, we save on I/O operations.
The buffer cache is located in the server’s shared memory and is structured as an array of buffers. Each buffer consists of space for one data page and a header. The header contains, among other things:
● Location of the page on the disk (file and page number)
● Buffer usage count (incremented each time the process reads or changes the buffer)
● A flag indicating that the data on the page has been modified and must eventually be written to disk (such a buffer is called dirty)
● A pin count tracking the number of processes currently working with the buffer content
The size of the buffer cache is set by the shared_buffers parameter. Changing this parameter requires a server restart.
The cache initially contains empty buffers, and all of them are chained into the list of free buffers. The purpose of the next victim pointer will become clear a bit later.
A hash table is used to quickly find the required page in the cache.
Page 4: Page in the Cache
 {#source-figure-004 caption=“Source slide page 4: Page in the Cache”}
Speaker notes
When a process needs to read a page, it first attempts to find it in the buffer cache using the hash table.
The file and the page number in the file are used as the hash key. The process finds the buffer number and quickly checks whether it really contains the page needed. As in any hash table, collisions are possible here; in this case, the process will have to check several pages.
If the required page is found in the cache, the process must pin the buffer (incrementing the pin count), and increment the buffer usage count. Since multiple processes can pin the same buffer simultaneously, a counter is used for this purpose, not a boolean flag.
While a buffer is pinned (pin count is greater than zero), the buffer is considered to be used and its contents should not change drastically. For example, a new tuple may be added into the page. This does not interfere with any operations due to multiversion concurrency control and visibility rules. However, a different page cannot be read into a pinned buffer.
Page 5: Page in the Cache
Create a table with one row:
Information about the contents of the buffer cache and its usage can be obtained using the pg_buffercache extension, which includes a view of the same name and additional functions:
For convenience, let’s create a view that decodes some of the columns. The condition for a database is required because the buffer cache contains data from the entire cluster. We can only decode information from the database we are connected to. Global objects are considered to belong to a database with OID 0.
The buffer cache already contains pages of the table; they appeared during the insertion:
The EXPLAIN command with the analyze and buffers options shows buffer cache usage during query execution:
Page 6: Page 6
The “Buffers: shared hit=1” line indicates that the page was found in the cache. After executing the query, the usage count increased by one:
Page 7: Reading into a Free Buffer
 {#source-figure-007 caption=“Source slide page 7: Reading into a Free Buffer”}
Speaker notes
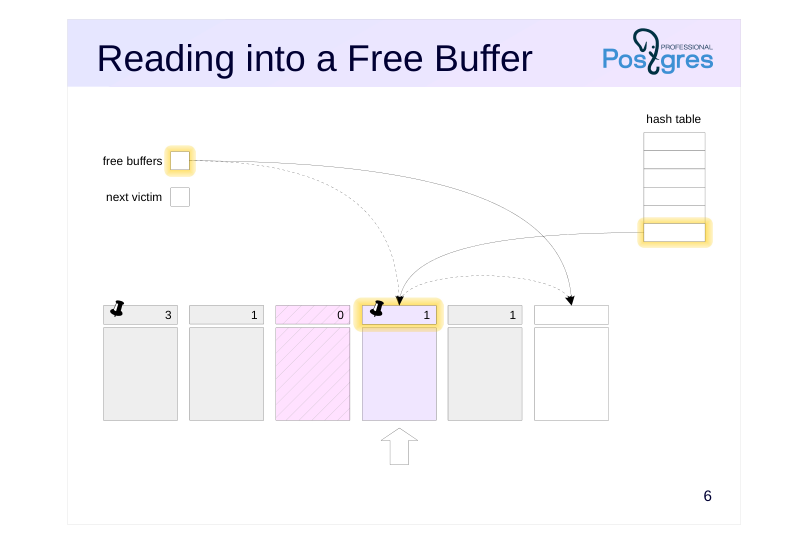
It may happen that the required page is not found in the cache. In this case, the page should be read from disk to any buffer.
If the free list contains buffers, one is selected from them first.
The buffer the pointer referred to is pinned, the required page is read into it, and the usage count is set to one.
The free buffer pointer moves to the next available buffer in the list, if any.
Besides, a reference to the loaded page must be written to the hash table so that it can be found in the future.
Page 8: Reading into a Free Buffer
 {#source-figure-008 caption=“Source slide page 8: Reading into a Free Buffer”}
Speaker notes
In the end, the last free buffer will be occupied.
Now the reference to a free buffer is empty. Consequently, in order to read a new page into any occupied buffer, we have to evict the page located there.
Buffers are returned to the free buffer list when a table is dropped or truncated, or when part of the tail pages are cut off during vacuuming, that is, in cases where the page in the buffer is not replaced by another one, but simply disappears.
Page 9: Reading into a Free Buffer
Let’s restart the server to reset the buffer cache.
There are free buffers in the cache:
Execute a query on the table:
The “Buffers: shared read=1” line indicates that the page had to be read from disk. Here it is:
The number of free buffers decreased:
Not only the read page got into the cache, but also pages of the system catalog tables that were needed by the planner.
Page 10: Reading with Eviction
 {#source-figure-010 caption=“Source slide page 10: Reading with Eviction”}
Speaker notes
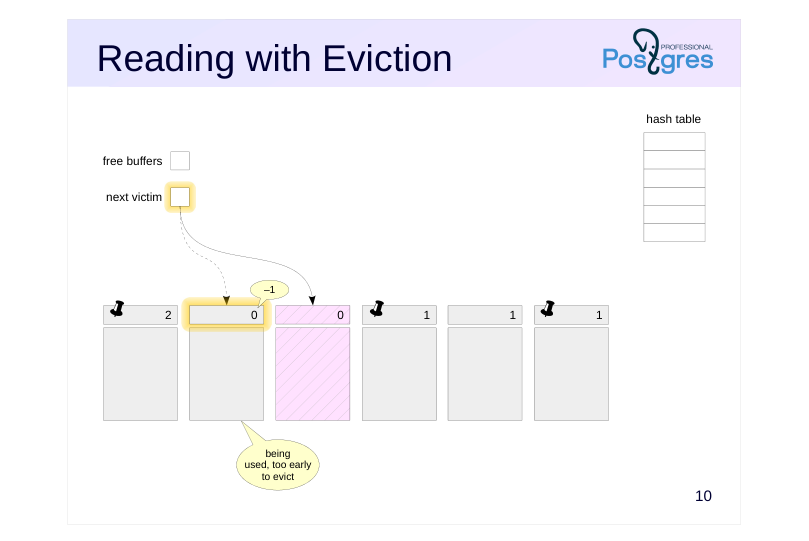
The eviction mechanism uses a next victim pointer.
The clock-sweep algorithm circularly goes through all buffers, decrementing their usage counts. The first buffer with a usage count of zero that can be occupied by a new page will be selected.
The higher the buffer’s usage count (the more often it is used), the more likely it is to remain in the cache. To prevent excessive looping when counts are large, the maximum value of the usage count is limited to 5.
In our example, the process first accesses the buffer by pointer. The buffer is pinned (i.e., used by some process), so its page cannot be evicted. Nevertheless, we reduce the usage count by one and proceed to the next buffer.
Page 11: Reading with Eviction
 {#source-figure-011 caption=“Source slide page 11: Reading with Eviction”}
Speaker notes
The next buffer is not pinned, but its usage count is greater than zero.
We reduce the counter by one, giving the page a chance to remain in the cache.
Page 12: Reading with Eviction
 {#source-figure-012 caption=“Source slide page 12: Reading with Eviction”}
Speaker notes
Finally, we reach an unpinned buffer with a zero usage count. The page in this buffer will be evicted.
However, in our example, the buffer appears to be dirty, i.e., it contains modified data. Therefore, its page needs to be saved to disk first. To do this, the buffer is pinned (to show other processes that it is in use), after which the page is written to disk.
This is hardly a good situation since the process that is going to read the page has to wait until another page’s data is written. This effect is alleviated by checkpoint and background writer processes, which are covered in the Checkpoint lesson.
Page 13: Reading with Eviction
 {#source-figure-013 caption=“Source slide page 13: Reading with Eviction”}
Speaker notes
Once the page from a dirty buffer is written to disk, a new page is read into the free buffer as described earlier.
The reference to the next victim now points to the next buffer, and the newly loaded buffer has time to increase the usage count while the pointer makes a full circle through the buffer cache and comes back around.
Page 14: Tuning
Settings
- ↑
- shared_buffers = 128MB
- Buffer cache should contain active data
- if the size is too small, useful pages are constantly evicted
- if the size is too large, overhead grows pointlessly
- first approximation is 1/4 of RAM
- Double caching should be considered
- if a page is not in the DBMS cache, it may be found in the OS cache
- OS eviction algorithm is not aware of the database-specific features
Speaker notes
The cache size is set by the shared_buffers parameter. The default value of 128 MB is too low.
What do we need to consider to choose the appropriate value? Even the largest database has a limited data set that is actively processed.
Ideally, this set (plus some space for one-time data) must fit into the buffer cache.
If the cache size is smaller, actively used pages will constantly evict each other, thus leading to excessive I/O operations. A key indicator of this is when all pages in the cache have a high usage count.
However, with a large cache size, overhead for its maintenance will increase.
It is usually recommended to take 1/4 of RAM for the first approximation. However, it is important to understand that the optimal value depends not on the size of the RAM, but on the specific data and workload.
Note that PostgreSQL works with the disk via the operating system, so double caching occurs: pages are stored both in the buffer cache and in the OS cache. Therefore, a cache miss does not necessarily lead to actual physical I/O. However, the OS eviction algorithm is not aware of database-specific requirements.
https://postgrespro.com/docs/postgresql/16/runtime-config-resource#RUNTI ME-CONFIG-RESOURCE-MEMORY
Page 15: Tuning Cache Size
Using the pg_buffercache extension, you can monitor the state of the cache from different angles. In addition to information about how a particular page is presented in the cache, you can, for example, see the distribution of buffers by their popularity.
The pg_buffercache_usage_counts() function returns a number of shared buffers for each possible value of usage count. Like the pg_buffercache view, the function does not use buffer manager locks, so when working concurrently in the database, a slight inaccuracy in the results of the function is possible. Let’s examine the cached proportion and usage activity for each table:
Another function from the extension will show us summary information about the buffer cache:
Such queries can hint at how actively the buffer cache is being used and provide food for thought on whether to increase or decrease its size. It is important to note that such queries should be run several times: the numbers will change within certain limits, and the overall set of results may be inconsistent. Information similar to what the pg_buffercache_summary() and pg_buffercache_usage_counts() functions return can also be obtained using the pg_buffercache view. However, using the functions is less costly, which is convenient for monitoring systems.
Page 16: Bulk Eviction
 {#source-figure-016 caption=“Source slide page 16: Bulk Eviction”}
Speaker notes
During operations that perform bulk data reading or writing, there is a risk of evicting useful pages from the buffer cache with one-time data. To avoid this, so called buffer rings are used: only a small part of the buffer cache is dedicated for each operation. The eviction is carried out only within the ring, so the rest of the data in the buffer cache is not affected.
If dirty buffers appear in the ring during operation, they will be either removed from the ring or flushed to disk.
Page 17: Buffer Ring
Sequential reading
- 32 pages
- dirty buffer is excluded from the ring
- Vacuuming
- vacuum_buffer_usage_limit = 32
- dirty buffer is flushed to disk and page is evicted
- Bulk Writing
- ≤2048 pages
- dirty buffer is flushed to disk and page is evicted
Speaker notes
During a sequential scan of a table, a buffer ring of 32 pages is used. If dirty buffers appear while processing this data (as a result of setting hint bits or performing an UPDATE), they are removed from the ring, returned to the main cache, and will be subsequently evicted according to the general rules. The buffer removed from the ring is replaced by another buffer from the main cache. Such a strategy is designed for scenarios where the data is mainly read, not modified.
If another process scans the same table, it attaches to the existing buffer ring and later reads the pages that have been evicted before.
Vacuum also uses a ring, its size is set by the vacuum_buffer_usage_limit parameter. The default value of the parameter is quite small (32 pages), since slowing down vacuuming is usually less critical than slowing down user processes (an exception is aggressive vacuuming, where it can use the entire cache).
For bulk write operations such as COPY or CREATE TABLE AS SELECT, the ring is quite large (usually 2048 pages, but not more than 1/8 of the buffer cache).
Page 18: Bulk Eviction
A buffer ring is used to fully read tables larger than a quarter of the buffer cache. Cache size (in pages):
Insert rows into the table:
Restart the server to reset the buffer cache.
And reset the overall I/O statistics:
Read data from the table:
All data pages were read, but how many cache buffers do they occupy?
When scanning a large table, the ring size is 32 buffers. PostgreSQL version 16 introduced the pg_stat_io view, which shows I/O statistics from the DBMS’s perspective (OS-level caching is not taken into account).
Page 19: Page 19
The row with the normal context shows read-write operations in the shared part of the buffer cache, and bulkread shows operations in buffer rings. reads — number of reads from files hits — how many times a page was found in the cache reuses — number of buffer reuses in the buffer ring The difference between reads and reuses in the bulkread row equals the ring size (32). Reset the statistics and update all rows in the table. In this case, buffers with pages will be detached from the buffer ring and remain in the cache:
Now the cache contains all or almost all pages of the table, the number of which has doubled due to new row versions:
Let’s take a look at the statistics again.
The table is fully scanned once again through the buffer ring. At the same time, 32 pages remained in the ring from the previous scan, and the rest had to be read again. The modified pages are transferred one by one to the main cache; accesses to them are counted in the normal row. At the same time, updating each of the 30 thousand rows of the table requires several page accesses, thus the value in the hits field is quite large.
Page 20: Local Cache
Temporary Tables
- visible to only one session, so there is no point in using shared cache
- exist within one session, so their loss in a crash is acceptable
- Features
- no locks required
- memory is allocated on demand within temp_buffers
- standard eviction algorithm
- buffer ring mechanism is not used
Speaker notes
Temporary tables are an exception to the general rule. Since temporary data is visible to only one process, there is no need for them in the shared buffer cache. Moreover, temporary data exist only within one session, so it does not need to be protected against failures.
A lightweight local cache is used for temporary data.
Since the local cache is accessible to only one process, it does not require locks. Memory is allocated on demand (within the limit set by the temp_buffers parameter), since temporary tables are not used in all sessions. The local cache uses a standard eviction algorithm.
At the physical level, temporary tables are stored similarly to regular tables. The temp_tablespaces parameter specifies the tablespaces where temporary objects (temporary tables and their indexes) will be created when CREATE command does not explicitly specify a tablespace.
The temp_tablespaces parameter value can contain a list of tablespace names. When this list contains more than one name, PostgreSQL randomly selects one from the list when creating each temporary object. However, for subsequent objects created within the same transaction, the tablespaces are sorted sequentially. If the list contains an empty string (default value), PostgreSQL will use the default tablespace for the current database.
Page 21: Temporary Tables
Create a table with one row:
In the query execution plan, access to the local cache looks like “Buffers: local”:
We see that inserting the row caused the table to extend.
Page 22: Cache Prewarming
pg\_prewarm extension
- manual prewarming of the OS cache
- manual prewarming of the buffer cache
- automatic prewarming of the buffer cache upon server restart
Speaker notes
After a server restart, the buffer cache is empty, and it takes some time for it to prewarm, i.e., to get filled with the current, actively used data. Sometimes it can be useful to immediately read the contents of certain tables into the cache.
The pg_prewarm extension allows us to read manually some tables either into the OS cache, or the DBMS buffer cache.
The extension also allows us to restore automatically the contents of the buffer cache after a server restart. To do this, we need to add the extension library to shared_preload_libraries parameter.
https://postgrespro.com/docs/postgresql/16/pgprewarm
Page 23: Cache Prewarming
Let’s consider the most basic scenario for using the extension to prewarm up the cache.
Restart the server once again to ensure that the test table data is not in the cache:
Calling the pg_prewarm function without additional parameters fully reads the main fork of the specified table into the buffer cache:
Page 24: Takeaways
All data access runs through the buffer cache
- Rarely used pages are evicted, frequently used pages remain
- Buffer cache reduces I/O, but requires logging
Page 25: Practice
- Create a table and insert a number of rows into it. How many a) pages on the disk, b) buffers in the cache does the table occupy?
- Find out the number of dirty buffers in the cache at the moment. Use CHECKPOINT command to perform a checkpoint. How many dirty buffers are left now?
- Load the pg_prewarm extension library, restart the server and check that the contents of the buffer cache are restored.
Speaker notes
To check the contents of the buffer cache, use the pg_buffercache extension:
https://postgrespro.com/docs/postgresql/16/pgbuffercache.html
Page 26: 1. Table in the Cache
Let’s create a table:
Run VACUUM to ensure we have all forks:
How many pages on disk does the table occupy?
The main fork is:
The free space map:
The visibility map:
How many buffers in the cache does the table occupy?
Page 27: Page 27
2. Dirty Buffers in the Cache
Let’s execute a checkpoint:
No dirty buffers remain. Checkpoints are discussed in detail in a dedicated lesson.
3. Automatic Cache Prewarming
Add the pg_prewarm library and restart the server.
Now, a separate background process will dump the list of pages in the buffer cache to disk every pg_prewarm.autoprewarm_interval time units.
Read table t into the buffer cache:
Page 28: Page 28
You can either wait, or dump the page list manually:
The file contains the database, tablespace, and file IDs, the fork number, and the page number:
Let’s restart the server again.
After startup, the background process will read all pages listed in the file into the buffer cache.
Reset the parameter.